
The Hong Kong Generative AI Research and Development Center (HKGAI) announced on September 18, 2026 the release of open-source music large model YuE2. The team says it is the world's first open-source music large model to unify creation, cover versions and editing under a "symbolic planning" framework; on the same day it ranked 4th across all of Hugging Face Trending (Trending Score 595), the only music model in the top five. Nine days after launch, the team's official model logged 11,626 downloads; including the ComfyUI wrapper, community GGUF/quantized versions and toolchains, the ecosystem has accumulated roughly 179,000 downloads.
HKGAI was established in October 2023 with funding from the AIR@InnoHK platform, which focuses on AI and robotics, and is led by the Hong Kong University of Science and Technology. Its R&D spans language, vision and audio. YuE2 is regarded as a key milestone in the center's audio generation work; the press release also borrows the phrase "DeepSeek moment for the music world" to describe the momentum of open-source models catching up with and even surpassing some commercial closed-source systems.
WildSongBench: best-of-8 composite score beats several commercial models
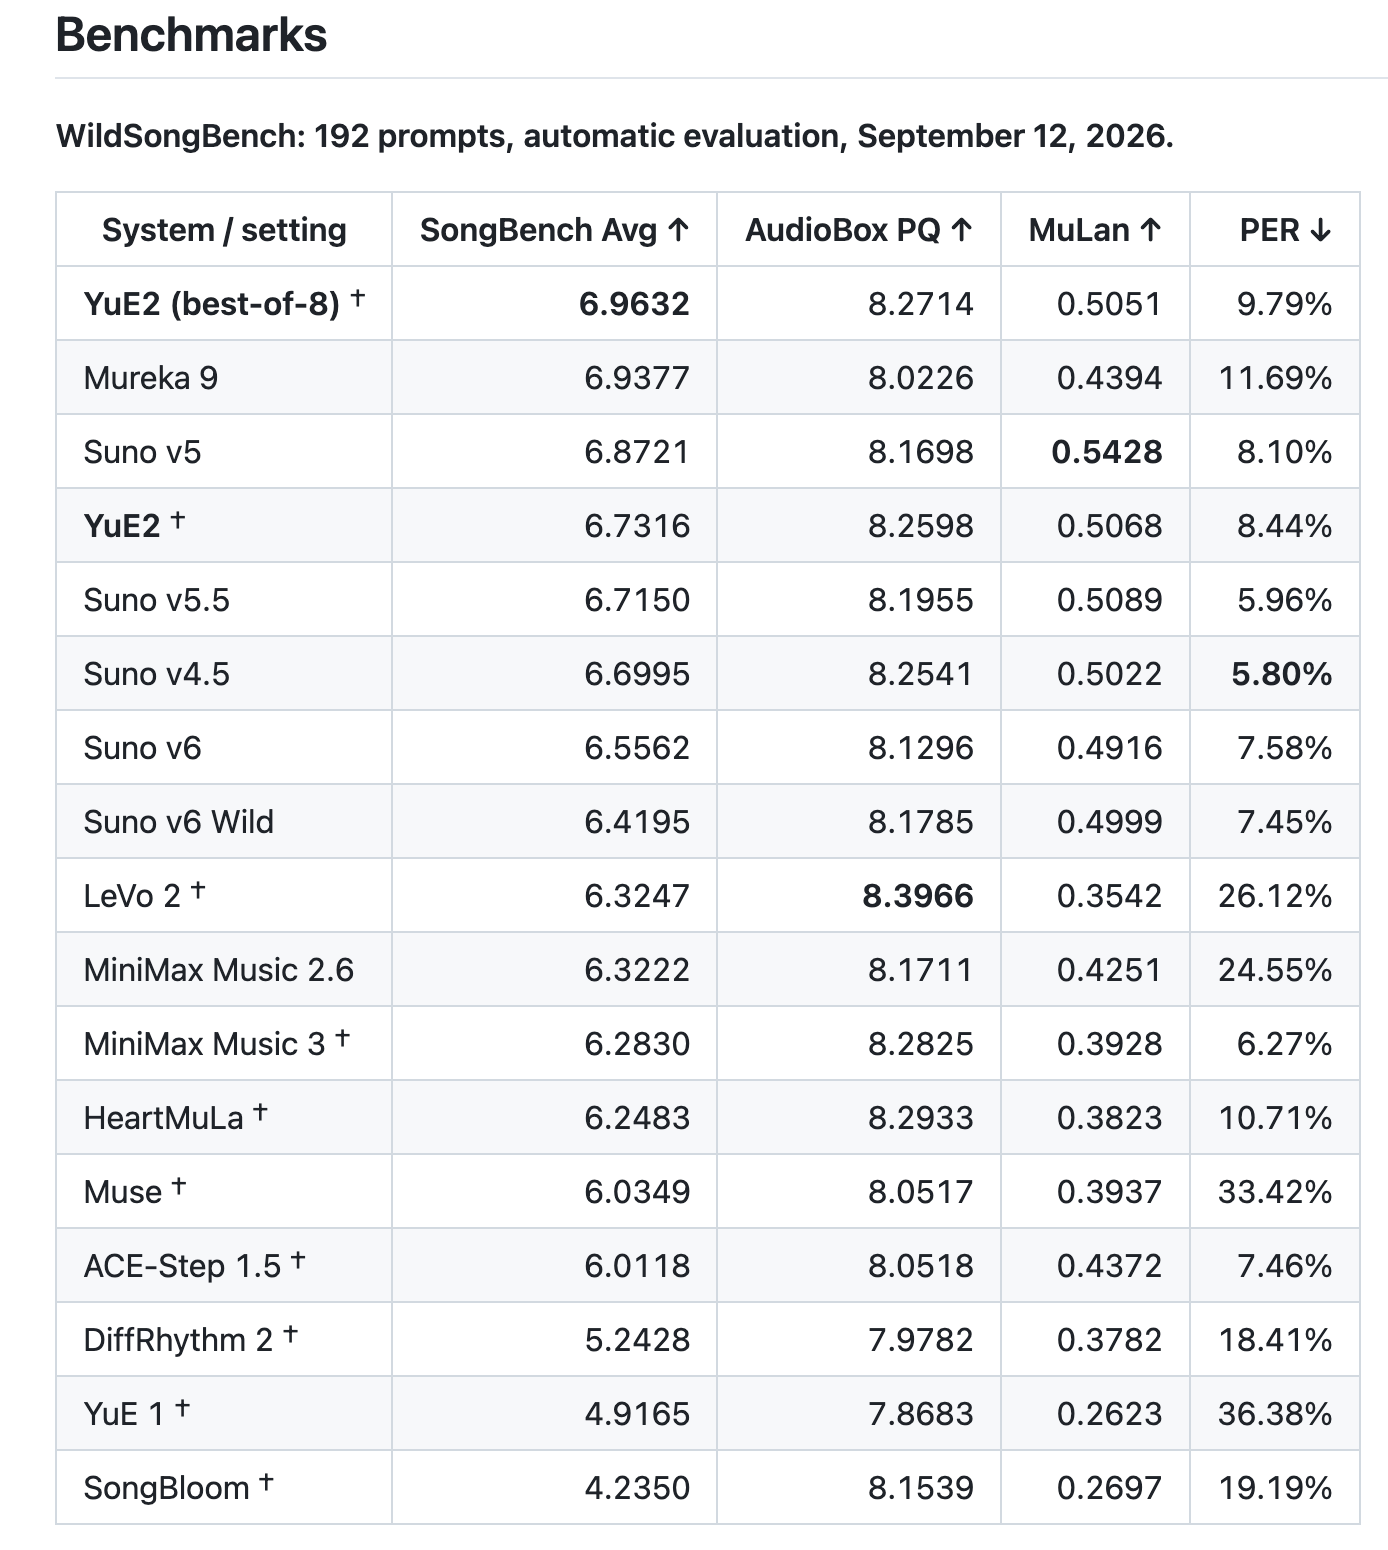
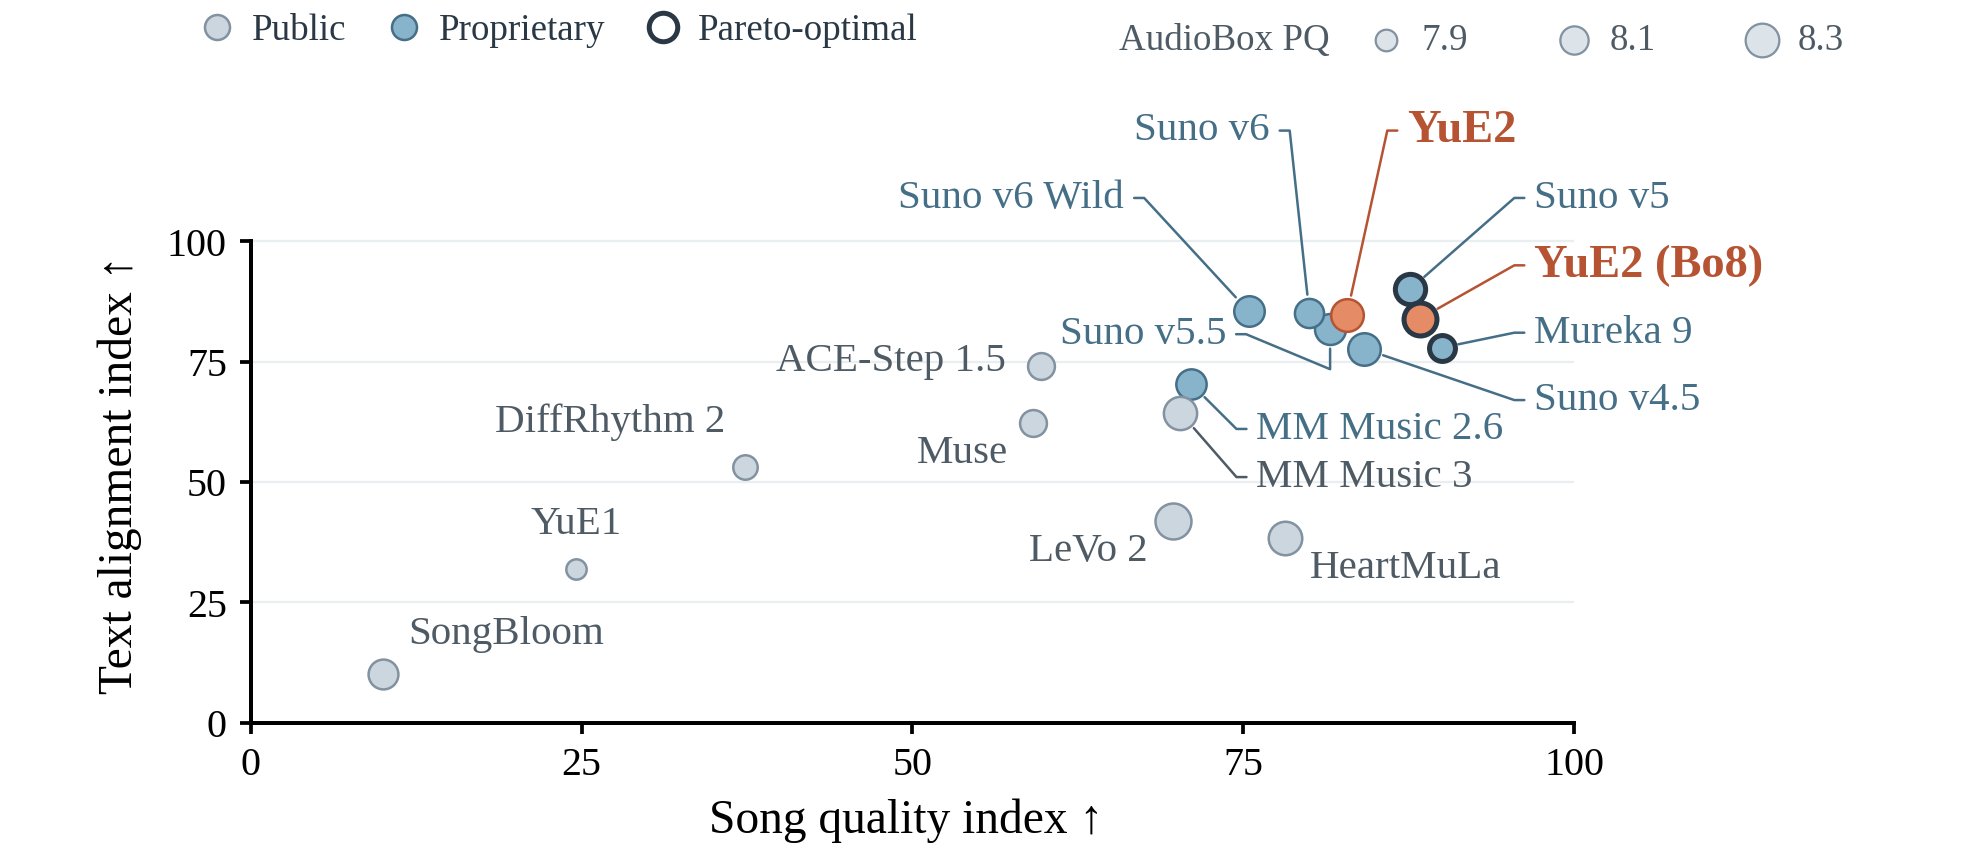
The WildSongBench evaluation runs an automated assessment over 192 prompts (September 12, 2026). The table shows YuE2 (best-of-8) topping the leaderboard with a SongBench Avg of 6.9632; a single YuE2 pass scores 6.7316. Comparable entries include Mureka 9 (6.9377), Suno v5 (6.8721), Suno v5.5 (6.7150) and Suno v6 (6.5562), with the previous-generation YuE 1 at 4.9165. YuE2 does not lead across every metric: Suno v5 has the highest MuLan score (0.5428), LeVo 2 has the highest AudioBox PQ (8.3966), and Suno v4.5 has the lowest PER (5.80%).
| System | SongBench Avg ↑ | AudioBox PQ ↑ | MuLan ↑ | PER ↓ |
|---|---|---|---|---|
| YuE2 (best-of-8) | 6.9632 | 8.2714 | 0.5051 | 9.79% |
| Mureka 9 | 6.9377 | 8.0226 | 0.4394 | 11.69% |
| Suno v5 | 6.8721 | 8.1698 | 0.5428 | 8.10% |
| YuE2 | 6.7316 | 8.2598 | 0.5068 | 8.44% |
| Suno v6 | 6.5562 | 8.1296 | 0.4916 | 7.58% |
| YuE 1 | 4.9165 | 7.8683 | 0.2623 | 36.38% |
White-box control: symbolic planning decoupled from acoustic rendering
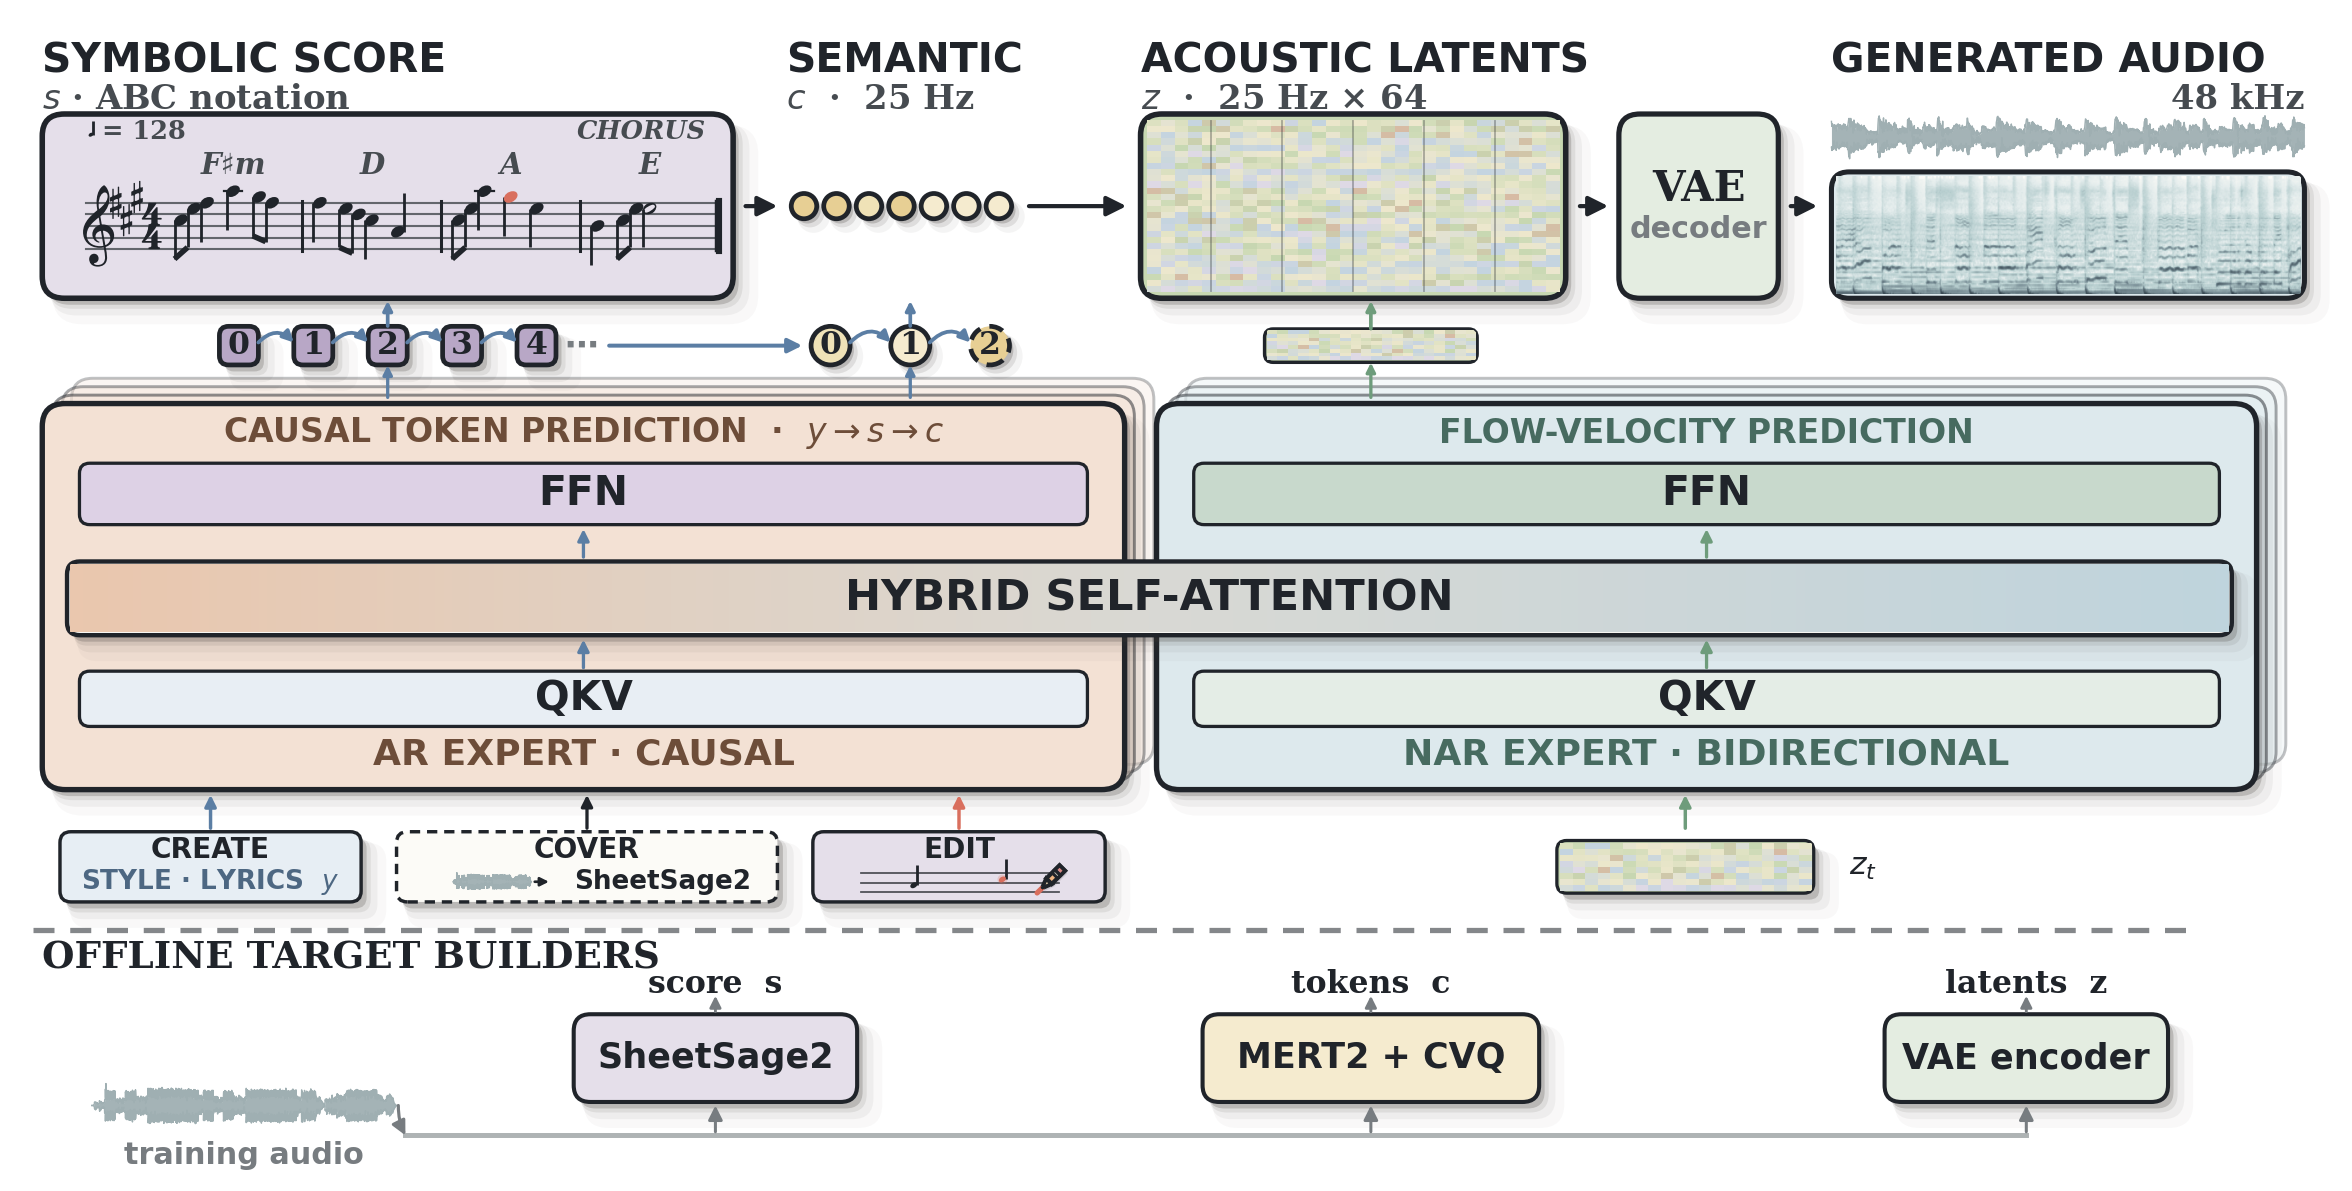
YuE2 separates "symbolic planning" from "acoustic rendering" and uses a mixture-of-experts (MoE) design to boost controllability: the AR expert uses causal attention to autoregressively predict ABC notation and a semantic skeleton; the NAR expert uses flow matching to predict acoustic latents; a VAE decoder then renders 48 kHz stereo output. Unlike black-box sampling where a prompt directly produces audio, creators can intervene at each step — tweaking a single note without redoing the whole track, or shifting style while preserving the original melody.
An official demo takes the Mandarin pop song "末班車" (Last Train) through nine rounds of conversational editing — re-harmonization, arrangement rework, weaving in the "Twinkle Twinkle Little Star" melody, developing variations and rewriting lyrics — before arriving at a structurally complete English jazz arrangement. Each step corresponds to a verifiable score and audio output, rather than another unrelated random generation.
Six languages, sixty genres, a local open-source ecosystem
On the capability side, YuE2 supports six languages including Chinese, English, Japanese, Korean, Russian and Spanish, covering more than 60 genres (including City Pop, heavy metal, jazz and flamenco). Weights are open-sourced and free to download (non-commercial use only), and the model can run locally on a single consumer GPU; commercial licensing requires separate negotiation. The team has simultaneously open-sourced a transcription tool, music understanding model and evaluation benchmark, stringing together a "transcription — creation — editing — evaluation" toolchain. Project entry: GitHub multimodal-art-projection/YuE.
- Open-source weights (non-commercial) plus single consumer-GPU local execution
- Creation / cover versions / editing unified within a symbolic planning pipeline
- Transcription tool, music understanding model and evaluation benchmark open-sourced alongside the model